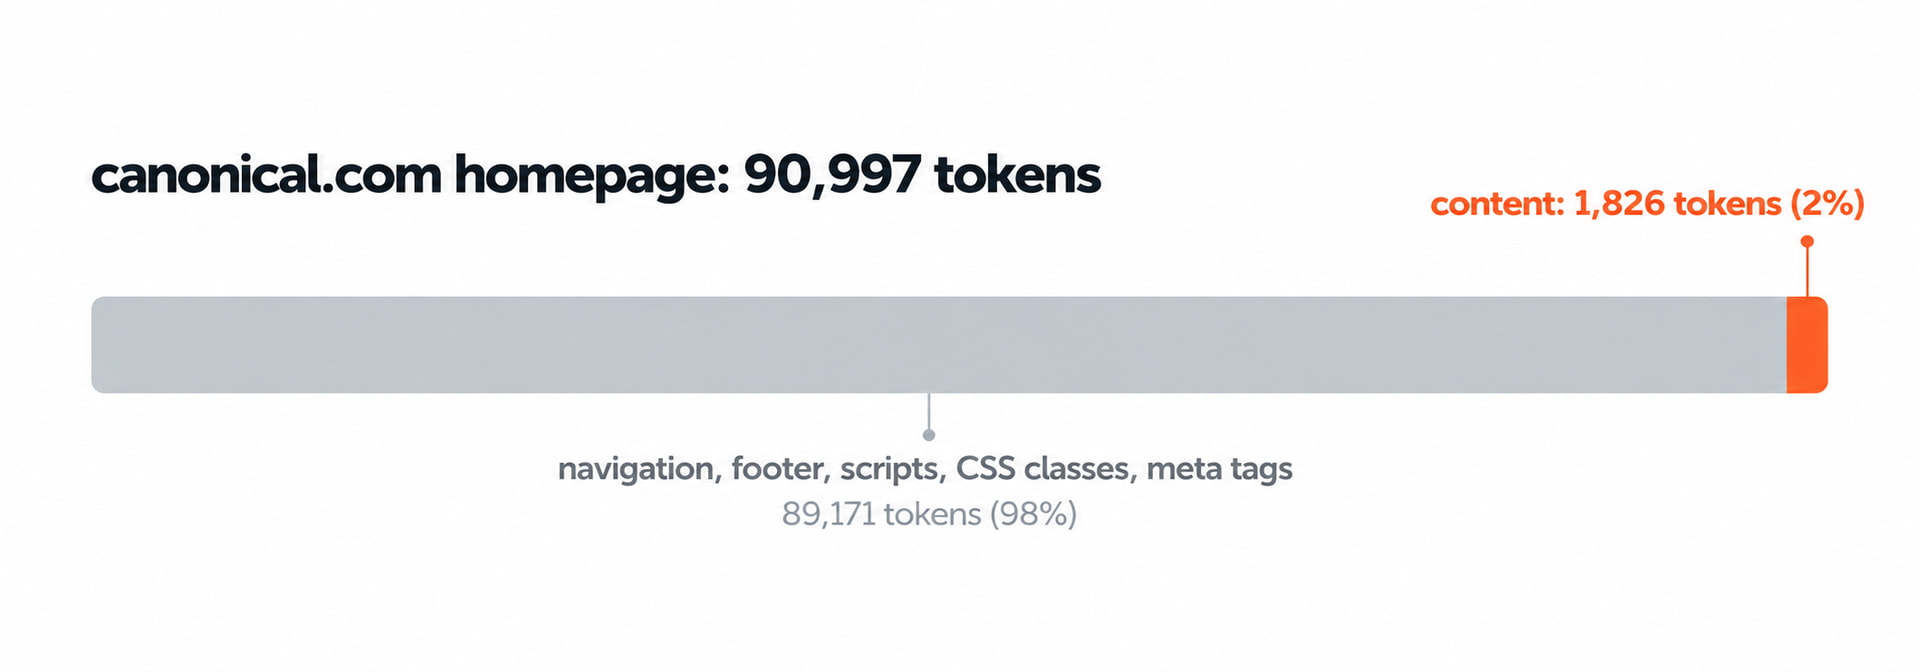
The HTML of the canonical.com homepage is about 91,000 tokens, the chunks of text AI models read and bill by. Only about 1,800 of those tokens are words a person would read. The rest is menus, footers, scripts and CSS, which a browser turns into a page and a program has to wade through.
A stakeholder found this out while trying to use our content with AI tools, and showed that Markdown helped. This post covers how I gave every page on canonical.com and ubuntu.com a clean Markdown version with one query parameter, and made it a package any of our sites can add with two lines of code.
Measuring the damage
I fetched a set of pages from both sites and counted their tokens with a real tokenizer. I used OpenAI’s o200k_base; other models split text a little differently, but the proportions hold.
import tiktoken, urllib.request

enc = tiktoken.get_encoding("o200k_base")
html = urllib.request.urlopen("https://canonical.com/").read().decode()
print(len(enc.encode(html)))  # 90,997
The heaviest page in the set was the canonical.com homepage, at 90,997 tokens. The thirteen pages I measured averaged about 46,000.
Don’t AI tools already clean pages up?
The big ones do. When ChatGPT, Claude or Perplexity browse a page, they strip scripts and styles and try to pull out the main content first. But that’s guesswork from the outside, and it can go wrong: menus slip through, content in tabs goes missing, and plain text loses the headings and links. Even the simplest cleanup of our homepage, which only removes scripts and styles, still leaves 4,636 tokens with the menu text mixed in.
Plenty of programs don’t clean anything. Developers building their own agents, scrapers and pipelines often fetch a URL and pass the response straight to a model. For them, the 91,000 tokens are real: at $1.25 per million input tokens (Gemini 2.5 Pro’s rate), $2 buys about 17 reads of our homepage, and one page fills most of a 128k context window.
Either way, the reader is guessing where our content starts and ends. We already know, so the site should tell them.
One query parameter
I kept the fix small. Take any URL on canonical.com or ubuntu.com and add ?format=md:
https://ubuntu.com/kubernetes/what-is-kubernetes
https://ubuntu.com/kubernetes/what-is-kubernetes?format=md
You get the same page as Markdown, with the page’s metadata at the top:
---
title: What is Kubernetes?
description: What is Kubernetes? Learn about container orchestration, cluster
  management, and how Ubuntu powers Kubernetes deployments.
url: https://ubuntu.com/kubernetes/what-is-kubernetes
---

# What is Kubernetes?

Kubernetes, or k8s for short, is an open source platform pioneered by Google...
Nobody has to write or maintain anything extra. The Markdown comes from the same page the browser gets, so if a page exists as HTML, it exists as Markdown.
Compared with the raw HTML that a direct fetch returns, the difference looks like this:
| Page | HTML tokens | Markdown tokens | Reduction |
|---|---|---|---|
| canonical.com | 90,997 | 1,826 | 50x |
| canonical.com/data | 71,398 | 1,419 | 50x |
| ubuntu.com | 57,411 | 2,603 | 22x |
| Ubuntu Pro | Ubuntu | 28,512 | 2,618 | 11x |
Across the thirteen pages I measured, the average dropped from about 46,000 tokens to 1,700, a 27x cut. Against a basic cleanup the gap is smaller (on the ubuntu.com homepage the plain text and the Markdown are about the same size), but the Markdown has what the plain text lacks: only the page’s own content, with headings, absolute links and metadata.
Useful beyond AI
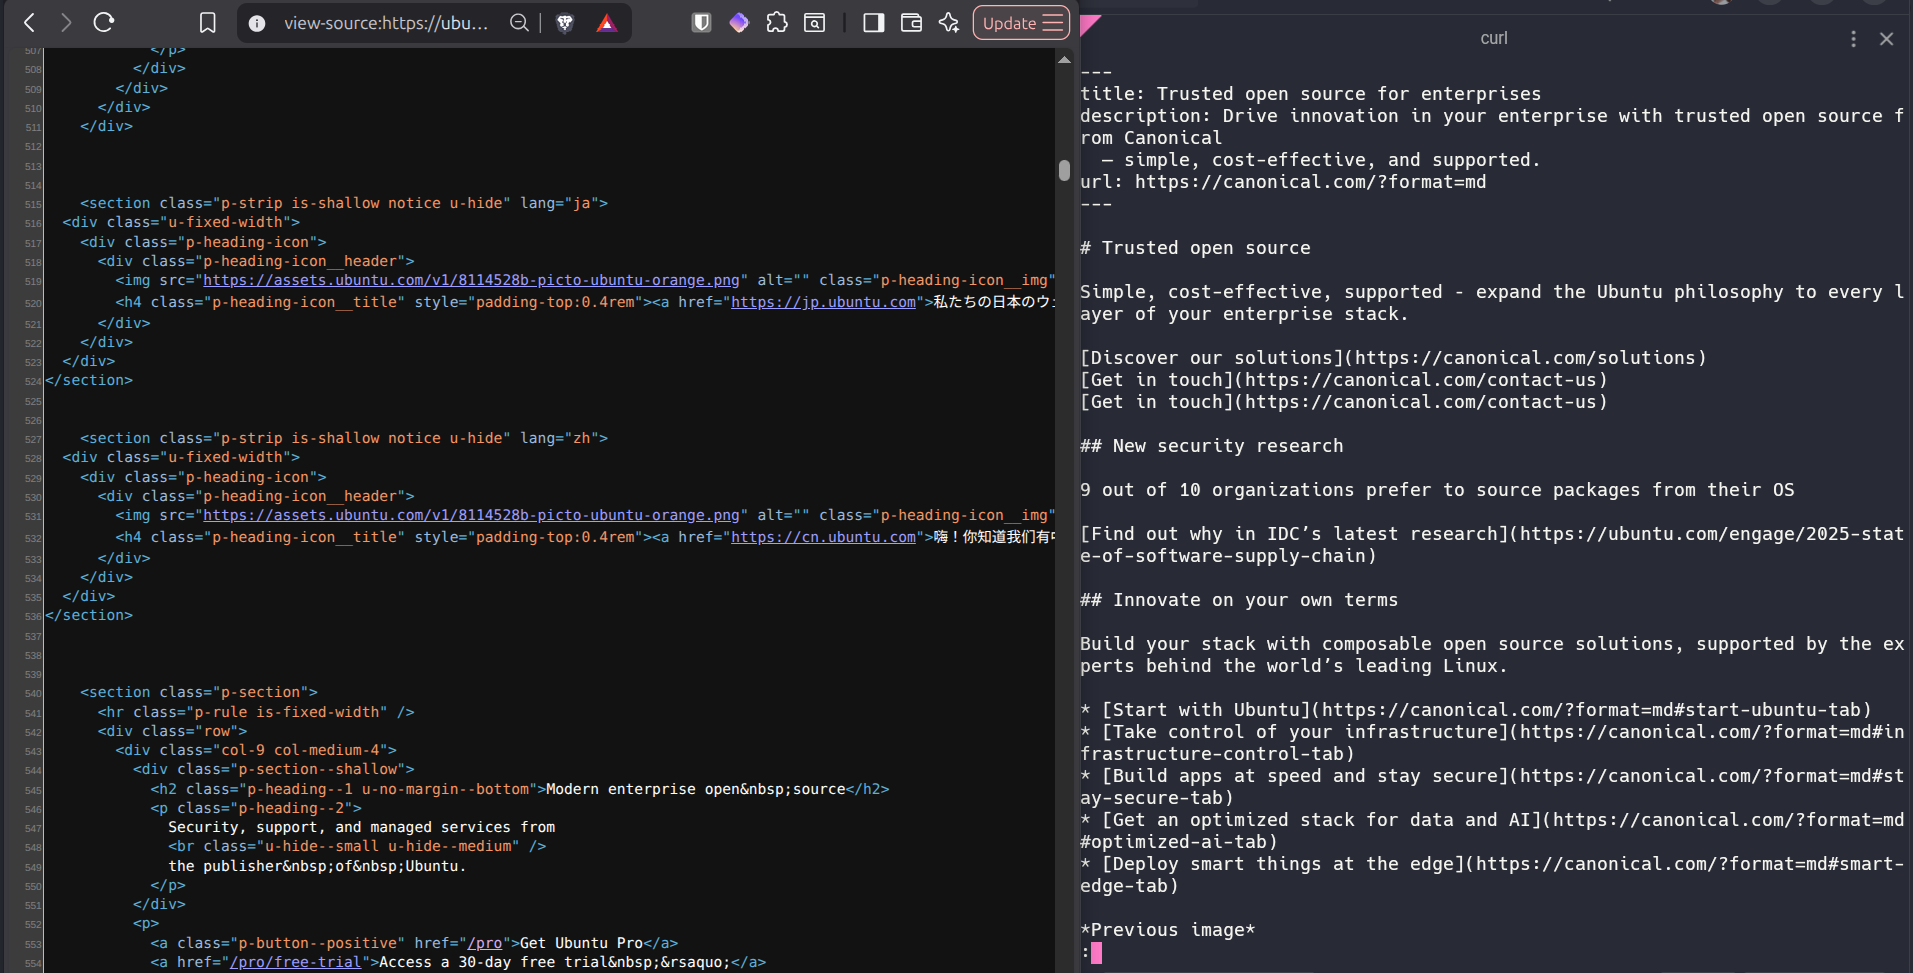
The Markdown is useful outside AI too. A colleague told me the Markdown versions helped with their own work, and if you just want the text of a page, you no longer need a scraper:
You can read a page in the terminal:
curl -s "https://ubuntu.com/pro?format=md" | less
How it works
Our sites are Python apps built on Flask, and the extension hooks into Flask’s after_request step. Every response already passes through there, so the page renders exactly as it would for a browser and gets converted on the way out, only when the parameter is present:
def _handle_markdown_request(self, response):
    if request.args.get(self.query_param) != self.query_value:
        return response
    if "text/html" not in response.content_type:
        return response
    if response.status_code != 200:
        return response
    ...
JSON, XML, redirects and error pages pass through untouched. A successful HTML page goes through three steps:
- BeautifulSoup finds the
#main-contentelement and discards everything around it. Inside that, it removes scripts, styles,<nav>,<noscript>and anything hidden with ouru-hideoru-off-screenutility classes. - markdownify converts what’s left into Markdown with ATX headings, drops images and collapses runs of blank lines.
- The
<head>meta tags become the frontmatter: title, description, canonical URL, author, publish date and tags. A reader gets the page’s metadata as structured data instead of guessing it from the body text.
If anything in that chain throws an error, the handler logs it and returns the original HTML, so the worst case is that someone gets the normal page.

The contact form problem
The first version still let too much through. Many of our pages end with a Marketo contact form, and nobody reading the Markdown needs forty fields about company size and job title.
So I stripped every <form>, which broke the tab selectors on some pages, because those are built with form elements too. Matching Marketo’s mktoForm_* IDs with a regex worked, but tied the converter to one vendor’s markup. The version that stuck lets the template owner decide:
<section class="p-section" data-md-strip>
  <form>This form won't appear in the Markdown</form>
</section>
Anything marked data-md-strip is removed before conversion. We’ve since used it for newsletter sign-ups, duplicate breadcrumbs and sections that only work with JavaScript.
Two lines per site
Nothing in the code was specific to canonical.com, and the Web team runs a lot of Flask sites, so I moved it into its own package, canonicalwebteam.markdown-response. On canonical.com and ubuntu.com, this is the whole integration:
from canonicalwebteam.markdown_response import MarkdownResponse

MarkdownResponse(app)
The content selector, the elements to strip and the parameter name are all configurable, and the defaults suit sites built on Vanilla, our CSS framework.
Try it
Add ?format=md to any page on canonical.com or ubuntu.com and compare it with View Source. If you run a Flask site, it’s a pip install canonicalwebteam.markdown-response away, and issues and pull requests are welcome on GitHub.
Have you used the Markdown versions for something? I’d like to hear what. And if a page gives odd output, do let us know.