A confession to start: for a while now, whenever I opened a fresh MIR bug template, a small part of me sighed at the wall of `TODO`s staring back at me. Not because the questions are bad — every single one of them is there because something, somewhere, once went wrong without it — but because answering them well means repeating the same careful, slightly tedious archaeological dig on every single package. Check the build. Check the dependencies. Check for embedded copies of other peoples’ code. Check, check, check - checkattack.
So I did what any reasonably bothered engineer does when faced with repetitive-but-important work: I automated the boring part and kept the interesting part for myself. The result is auto-mir, an early-beta tool now living at a not yet proposed branch, and this post is me telling you about it — what it does, why it’s built the way it is, and why I’m not going to tell you that you have to use it.
A queue that doesn’t get a speed boost by itself
Main Inclusion Review exists for a good reason: before a package can become part of the default, supported Ubuntu experience in main, someone has to check it won’t quietly become tomorrow’s maintenance headache. The MIR process provides such a check and consists of three main steps (simplified): 1. A reporter thinks the case through 2. A reviewer checks it 3. Found issues get resolved. The team’s own service level objective is honest about the maths behind that: about one review per active member per week, which makes a max of roughly four cases handled in total, every week, forever. There are exceptions around feature freeze, when everyone dumps their MIR at the last minute and the queue predictably clogs.
The same page has a nice piece of advice buried in it for whom it may concern: “a well-prepared case will pass through more quickly”. That line is underselling itself. It’s really saying that reviewer time might be the scarcest resource in the whole pipeline, and the best lever anyone has to make sure their MIR completes the process swiftly is making sure nothing is left for the reviewer to go and dig up themselves.
Here’s the thing that quietly worries me, though: coding assistants, review copilots, and test generators are getting faster every quarter, and everyone is watching that space. Fewer people are watching the space right next to it — the processes, the gatekeeping, the “does this actually meet our bar” checks that don’t produce a shiny diff but instead decide whether everything upstream of them was worth doing. If code gets written and merged ten times faster in a few years but the checks around it are still exactly as manual as they are today, we haven’t sped anything up — we’ve just moved the traffic jam a bit further down the road, right in front of the one tollbooth that never got more lanes.
Neither good nor evil, just a tool with a mindset attached
Let’s get the obvious tension out of the way, because I’d rather have this conversation than not: using AI for something like package review can sound either exciting or alarming, depending on who you ask, and both reactions are a bit too fast. AI is neither good nor evil here — it’s a lever, and like any lever it depends entirely on who’s pulling it and how carefully.
Do it without a human in the loop at all, and you’ve handed over judgment calls that were never meant to be automated — that’s a loss of control, full stop. Refuse to touch it at all, forever, on principle, and the manual process quietly falls further behind everything around it, which is its own kind of failure, just a slower one. The middle ground — the one auto-mir is built for — is to let a human stay entirely in charge of the parts that require judgment, and let a machine carry the parts that don’t.
On a practical level, that means auto-mir is not pushy about it.
- You can use it fully, with model assistance switched on.
- You can run it in a mode with no AI involved at all (
--no-llm), where it might still be a helpful, standardized, deterministic evidence-gatherer but nothing more. - Or you can ignore it completely and keep doing MIRs exactly as you always have, by hand, from the template, the way it’s been done for years.
All three are legitimate choices. This is a tool you opt into, not a rule you’re now expected to follow.
How it actually thinks: facts first, AI last, human always
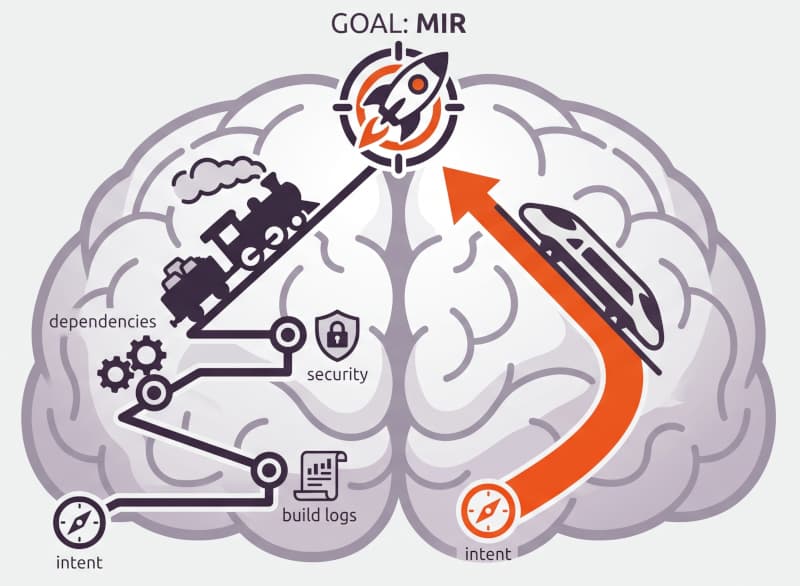
The auto-mir architecture is deliberately boring in the most important places, with no fancy trend-of-the-day. Even the AI insisted on keeping it simple, since there would be no benefit gained from autonomous concurrent agents, loops or any such features — it was a straight train of thought and tasks for a human, and now that train runs at high speed with only a few stops left for you to provide input.
- Deterministic evidence, first and foremost: Before anything resembling AI gets a say,
auto-mirspins up a clean LXD guest, builds the package, and gathers the same raw facts a reviewer or reporter would otherwise dig up by hand — dependency graphs, lintian output, CVE history, autopkgtest results, the package’s current archive component, embedded/static libraries, and so on. None of this is guessed. It’s the same manual legwork, just done consistently and without a bad Friday afternoon affecting the outcome. - Intent stays human: The one thing no adapter can gather is why someone wants a package in
mainin the first place, and what that package is actually for. That’s asked directly, from the person who knows, and never synthesized from evidence after the fact. - AI only where interpretation is genuinely needed: In practice, that’s often a fairly small, fairly confident judgment call, like turning a wall of build-log noise into “this fails because of a missing test dependency”. Findings that come out of that step are explicitly capped at medium confidence in the report; they render differently from deterministic findings, and they never get quietly promoted to “fact.”
- Everything compiles into one report: Before, you had a blank template and a long list of TODOs staring at you. Now you get a draft that’s ~90% filled in, with every deterministic fact, every human answer, and every AI-assisted suggestion labeled as what it is — and you still need to read every line before it goes anywhere near Launchpad.
There’s a bit of quietly responsible engineering wrapped around that AI step too. API credentials never leave the host machine, are never written into the disposable build guest, and are actively redacted from every log and artifact the tool produces. It will not be perfect and none of that is glamorous, but it’s the difference between “we added AI” and “we added AI responsibly,” and I’d rather spend the effort there than on a flashier feature.
Or keep every byte on your own box
By default, `auto-mir` runs against OpenRouter with a small/large model pair (currently z-ai/glm-4.7 and z-ai/glm-5.2), which turned out to provide good reasoning at a reasonable price and performance. But that’s just a sensible starting point, not a requirement — point the environment OPENAI_API_BASE elsewhere and, if needed, select different models via commandline parameters. The tool is happy talking to another endpoint, including a local model if you’d rather keep everything on your own machine entirely.
A recent post showed how to point OpenCode at a local Gemma snap instead of a hosted model, and the same trick works for auto-mir almost unchanged.
The only prerequisite is something that can actually run a model. I recently picked up a small box for AI experiments that handles models up to about 20GB — nothing exotic, a Ryzen AI 9, and it’s not blisteringly fast, but perfectly reasonable for this. Yours doesn’t have to look anything like mine; anything that can host a model will do.
For quick access to that capability I like the inference snaps:
sudo snap install gemma4
That alone auto-detected ROCm on my machine and pulled in whatever it needed. A quick status check confirms it’s alive and shows where it’s listening:
$ gemma4 status
engine: amd-gpu
services:
    server: active
    server-webui: active
endpoints:
    openai: http://127.0.0.1:8336/v1
    webui: http://127.0.0.1:8337/
model:
    name: gemma4-e4b-q4-k-m
gemma4-e4b-q4-k-m it is. With that in hand, pointing auto-mir at it instead of OpenRouter is just environment variables and two flags:
OPENAI_API_BASE=http://127.0.0.1:8336/v1 \
    ./auto_mir.py review 2161382 \
    --llm-model-small gemma4-e4b-q4-k-m --llm-model-large gemma4-e4b-q4-k-m
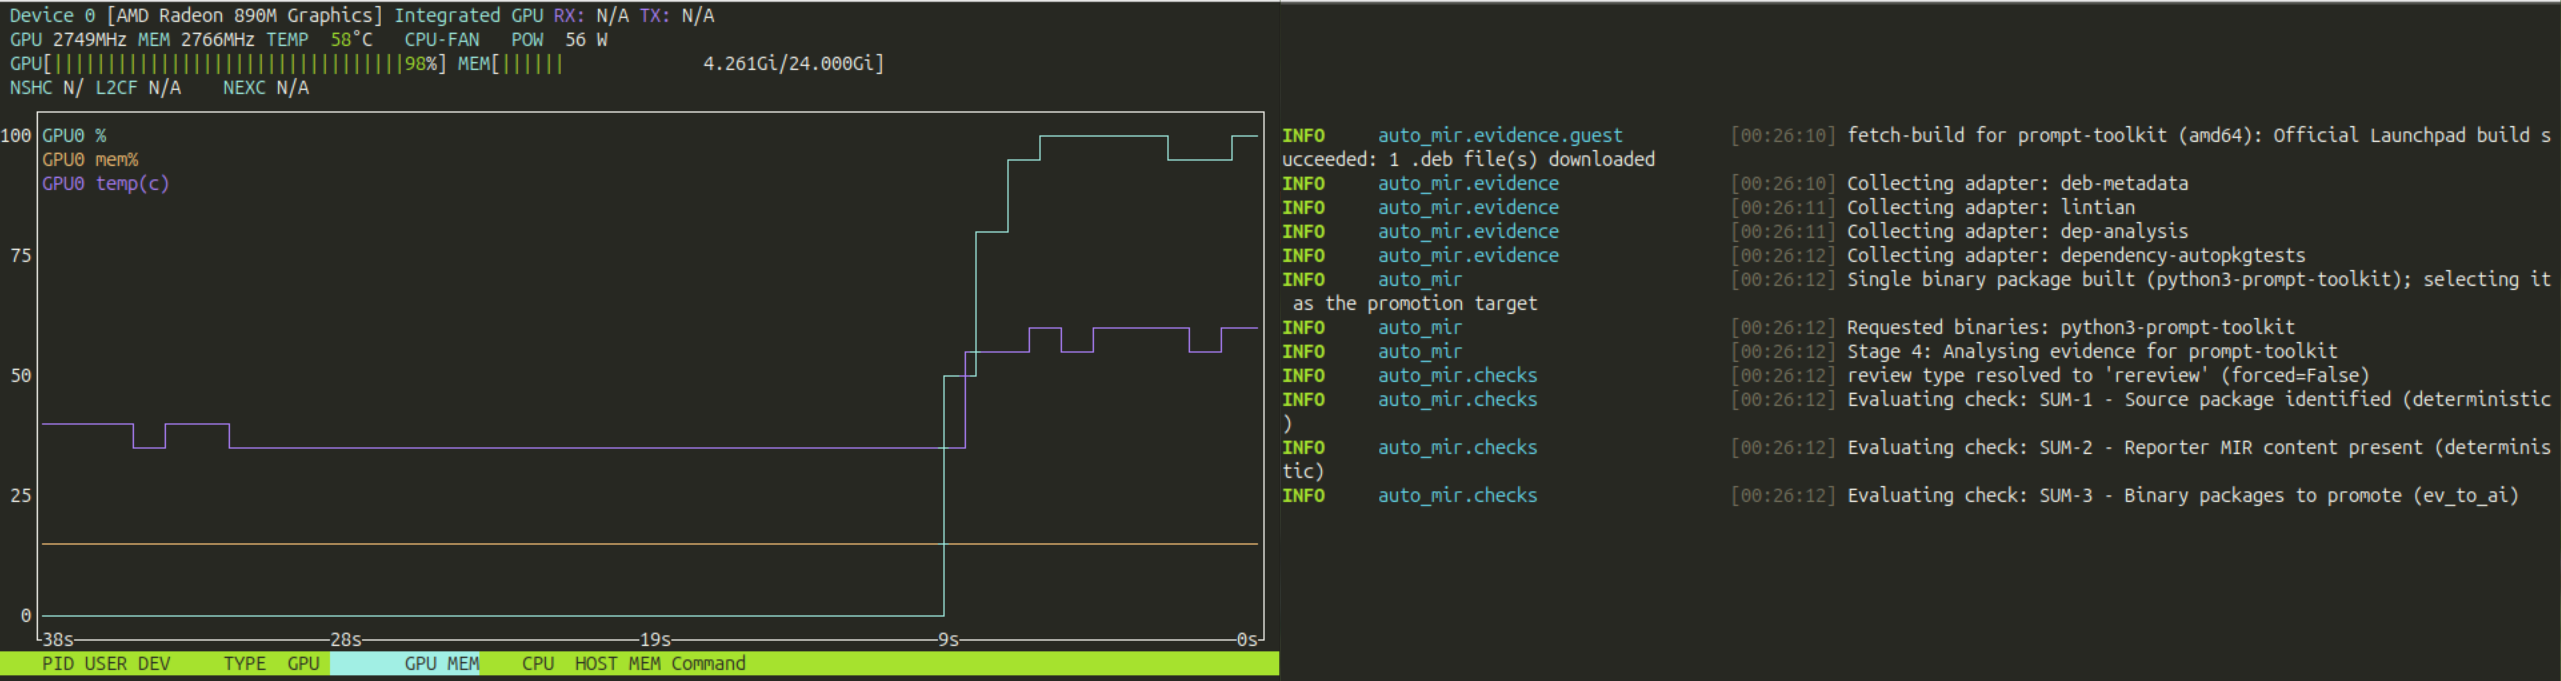
From there, the tool runs exactly as before and ends with the same kind of draft to review — except this time not a single byte left my machine to get there. The following shows my GPU busy processing the requests on the left while auto-mir on the right worked through its checks one by one.
Still your name at the bottom
None of the above changes who’s accountable. auto-mir never posts to Launchpad and never hands out an ACK or a NACK — a human does both, always.
An exit code of zero means the pipeline ran to completion, nothing more; it does not mean the package is ready, or that every check passed. A reporter draft can (and honestly, often should) come out the other end still containing blockers and TODOs, because that’s an accurate reflection of reality, not a bug.
The tool makes the “before” state of your review or request much less blank. It doesn’t make the “after” state someone else’s responsibility. You still post it in your own name, which means you still own it.
The first real cases
The first time reviewer mode ran against a real, live MIR was bug 2161382 (prompt-toolkit), and — appropriately, given the subject of this whole post — it immediately taught me something a synthetic test case never would have: a generic duplicate-package search cheerfully cited curl, openssl, and network-manager as “similar” candidates to a terminal input library, purely because their descriptions happened to share the words “command line.” A human reviewer would never make that mistake; a slightly too-literal text match will do so, happily, all day long. Of course this is fixed now, but that’s exactly the kind of thing you want to find in week one of real usage and it’s a big part of why this tool is still labeled “beta”.
Even more satisfying was an early encounter with report mode. The package I processed lacked both build-time tests and autopkgtests, which the tool immediately flagged as an open requirement. When it pressed me for input about something else, I — testing in a hurry — lazily replied that autopkgtests would cover it. The final cross-check hit back immediately, questioning how I could claim coverage when those tests didn’t exist. Not only was it right, it mirrored the exact conversations I’ve had with MIR reporters a dozen times over. At that moment, I realized the tool was already doing some of the work of a reviewer, making the reporter aware of the gaps before I even had to take a look.
From reviewers to everyone involved
auto-mir started life purely as a reviewer’s tool — so often have MIR members sighed and said “we should have a tool for that” that it was time to create it. Therefore review <BUG> reads an existing Launchpad MIR and produces a structured draft to check against. But the two sides of an MIR bug are asking for the same kind of care, just from opposite ends, and it turned out the reporter’s side of the process needed this just as much: there are far more people filing MIRs than there are members of the MIR team reviewing them.
So report <SOURCE> followed, walking a reporter through the preparation of an evidence-backed request from a terminal, one honest question at a time. What began as something for a small team is, conceptually, useful to a much larger slice of the Ubuntu developer community — anyone who’s ever wanted a package promoted and faced that same template.
Try it, or don’t — either is fine 
This is genuinely early: it works well for me, and for the handful of people who’ve started poking at it, but it hasn’t yet seen the mileage that would let me call it anything more than beta. If you’re curious, have a look at the branch and see the README for quick start instructions.
If you try it — whether on a real MIR or just kicking the tires — I’d genuinely like to hear how it went, what broke, and what you’d want it to do differently. Send it to me at christian.ehrhardt@canonical.com with auto-mir: at the start of the subject line, so it doesn’t get lost too easily. To make the post-mortem on your report a bit smoother, please include a tarball of that directory in /tmp the tool left behind.
Once the auto-mir tool has matured enough to be in regular use and merged, such communication would — like all else in the repo — move to issues and pull requests on GitHub where it belongs — but for a beta this early, a direct note works best.
And if none of this is for you — if you’d rather keep doing MIRs exactly the way you always have, template and all — that continues to be a perfectly good way to spend an afternoon. The TODOs aren’t going anywhere.
Happy reporting and reviewing, everyone!