Making local LLM behaviour visible with OpenTelemetry and COS Lite
A local large language model (LLM) does not need to crash to provide a poor
experience. It can take too long to begin, pause between output chunks, or
consume more memory and tokens than expected.
Observability can make this behaviour visible. An instrumented model path can
show how long a response takes, when its first output appears, how many tokens
it consumes, and whether it completes successfully.
This article explores what becomes possible when a local model emits these
signals through OpenTelemetry and brings them together in COS Lite and Tempo.
The example uses Ollama and a small gateway, but it is not a required
architecture. The same ideas can be adapted to other model servers and
observability systems.
A possible architecture
One way to observe a local LLM is to place a small FastAPI gateway between the
model and its clients. Applications can keep using an OpenAI-compatible chat
API while the gateway records what happens during each request.
This arrangement can:
- measure total duration, time to first response chunk, gaps between chunks,
and token usage; - emit metrics, logs, and traces with OpenTelemetry;
- route that telemetry through an OpenTelemetry Collector;
- store metrics in Prometheus, logs in Loki, and traces in Tempo, then explore
them through Grafana; and - compare normal, slow, token-heavy, and low-quality model behaviour.
The request and telemetry paths look like this:
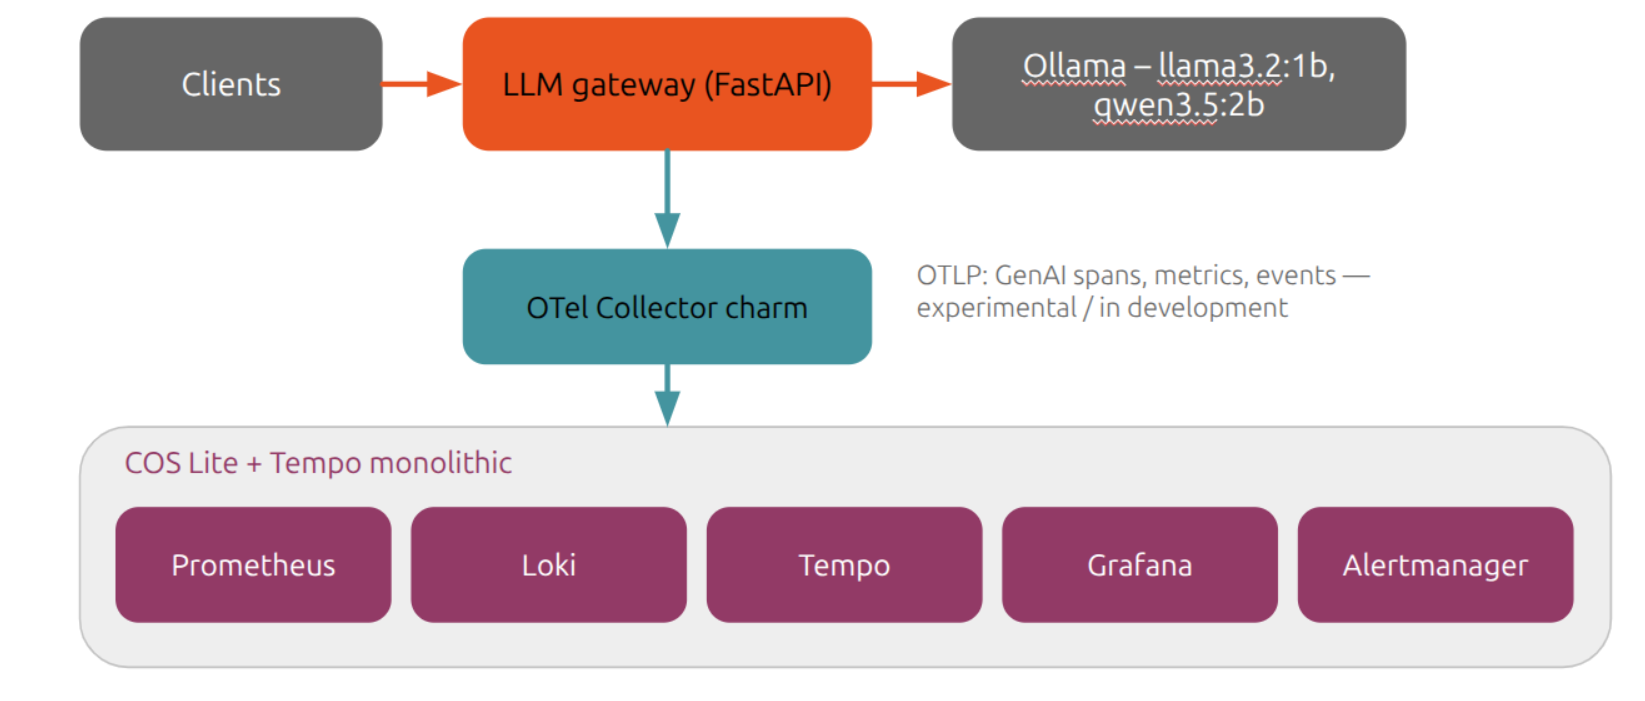
The orange path in the diagram is the model request. The teal path carries
OpenTelemetry data to the observability backends.
The base COS Lite bundle includes Prometheus, Loki,
Alertmanager, and Grafana. Tempo is added separately for tracing,
as the diagram’s “COS Lite + Tempo” label indicates.
Within COS alerting, Prometheus evaluates rules over the model
metrics. Alertmanager then groups and routes firing alerts to configured
receivers, such as email or an on-call system.
In this experiment, COS Lite runs on MicroK8s inside an Ubuntu virtual machine.
Canonical documents this deployment shape in its COS Lite on MicroK8s
tutorial.
For readers who want implementation artifacts, the public self-hosted LLM
observability reference project contains an example gateway,
Collector configuration, dashboards, traffic scenarios, and alert rules.
The repository is a demonstration and learning resource, not a supported
end-to-end installer.
Model serving and observability have different roles
The model server and the observability layer have different jobs. The model
server performs inference. The observability layer describes what happened as
a request moved through that inference path.
An OpenAI-compatible API provides a useful boundary between the two. A client
can keep the same request format while the model, quantization level, or
serving software changes behind that boundary.
This also makes comparisons more meaningful because each request can be
measured in the same place.
The example uses Ollama with CPU-friendly models. Ollama supports parts of the
OpenAI API, including chat completions, but it is not essential
to the observability pattern.
A gateway can provide an observation point
Instrumenting a gateway gives us one consistent place to observe model
requests. It can also avoid giving every client application its own
model-specific telemetry integration.
For both non-streaming and streaming requests, the gateway can create one trace
span per request. It can record total duration, token usage, and finish reason
in both modes.
For streaming requests, it can also record the first output chunk and gaps
between subsequent chunks.
Structured logs can include the trace and span identifiers needed to connect a
log entry to the request that produced it.
Token counts should be labelled accurately. A model server may report them;
otherwise, a gateway may have to estimate them, and an estimate is not
interchangeable with the model tokenizer’s count.
The current GenAI span conventions treat model instructions,
inputs, and outputs as sensitive and potentially large. Their content fields
are opt-in.
In this experiment, content capture is disabled by default. Operational signals
remain useful without exporting the conversation itself.
The observation point could instead be a model server, client library, or
application. What matters is that the signals describe the model interaction,
not which component records them.
The experience can be measured from more than one angle
Total response time gives only an outline of the experience. A streamed answer
can begin quickly and then stall, or begin slowly and finish in a burst.
| Question | Signal | What it can reveal |
|---|---|---|
| When does the answer begin? | Time to first response chunk or visible output | The initial wait before the user sees the answer |
| Does the answer keep flowing? | Time between output chunks | Pauses or stalls after generation has started |
| How long does the request take? | Total duration | The complete time spent on the model interaction |
| How much work does it represent? | Reported or estimated input and output tokens | The relative size of the context and generated answer |
| How did generation end? | Finish reason and errors | A normal stop, truncation, or a failure in the model path |
| Was the answer useful? | Optional quality evaluation | A fast and efficient response that still misses the task |
For an inference provider, these measurements can become service-level
indicators (SLIs). They make it possible to define service-level objectives
(SLOs).
For example, an SLO could set a target for the proportion of streaming requests
whose first response chunk arrives within a chosen threshold over a defined
period.
Similar objectives can be built around total duration or model-path error
rates. Appropriate thresholds depend on the model, hardware, workload, and
expected user experience.
The current OpenTelemetry GenAI client metrics cover
operation duration, token usage, time to first chunk, and time between
subsequent output chunks.
The first transport chunk is not always the first text a user can see. If user
experience is the goal, define whether empty metadata chunks count and label
the measurement clearly.
These signals are complementary, not a single scorecard. A long answer may be
appropriate for one task and wasteful for another. A short initial wait may
feel responsive even when the full answer takes longer.
Quality evaluation is application-specific and is not part of the shared metric
set. A heuristic, reference answer, or another evaluator can each address a
different question.
As of August 2026, the GenAI conventions remain Development in a
dedicated OpenTelemetry repository. Instrument names and attributes can change
as the conventions mature.
OpenTelemetry’s maturity policy says Development components may
change or be removed and should not be used in production.
OpenTelemetry puts the measurements in a shared context. Metrics can show
patterns across requests, traces can explain one request, and correlated logs
can add events and error details.
COS Lite and Tempo can bring the signals together
OpenTelemetry separates the way telemetry is produced from the place where it
is analysed.
In this example, a Collector receives OTLP data from the gateway and exports
metrics to Prometheus, logs to Loki, and traces to Tempo. Grafana provides a
common place to query and explore those backends.
The Collector pipeline keeps the model-facing component from
needing to know how every backend works. The application emits telemetry once;
receivers, processors, and exporters handle the next steps.
Processors can batch, transform, or filter telemetry. This also leaves room to
change a backend without changing the model API.
Prometheus can evaluate alert rules over aggregated model metrics. Alertmanager
then manages the resulting alerts by grouping and silencing them and routing
notifications.
For example, rules can detect sustained increases in time to first chunk, token
usage, or model-path error rates. Thresholds remain specific to the model,
hardware, workload, and user expectations.
From a pattern to one request
The value of collecting several signals becomes clearer during an
investigation. If a dashboard shows a rise in time to first chunk, the question
becomes: which requests are slower, and what do they have in common?
One investigation can move through the signals in this order:
- Metrics reveal the pattern across requests and compare dimensions such as
model, operation, or time period. - A linked exemplar or trace identifier narrows the investigation to one request.
The trace shows its timing and model-related attributes. - Correlated logs add events, finish details, or error information from the
same request.
This path depends on carrying trace context into logs and configuring exemplar
or data-source links. Collection alone does not create those links.
The trace below comes from one deliberately token-heavy request in the recorded
experiment. It took 50.87 seconds and produced its first output after 23.22
seconds.
It generated 476 output tokens. Those details appear alongside the model and
scenario without requiring the prompt itself to appear in the trace.
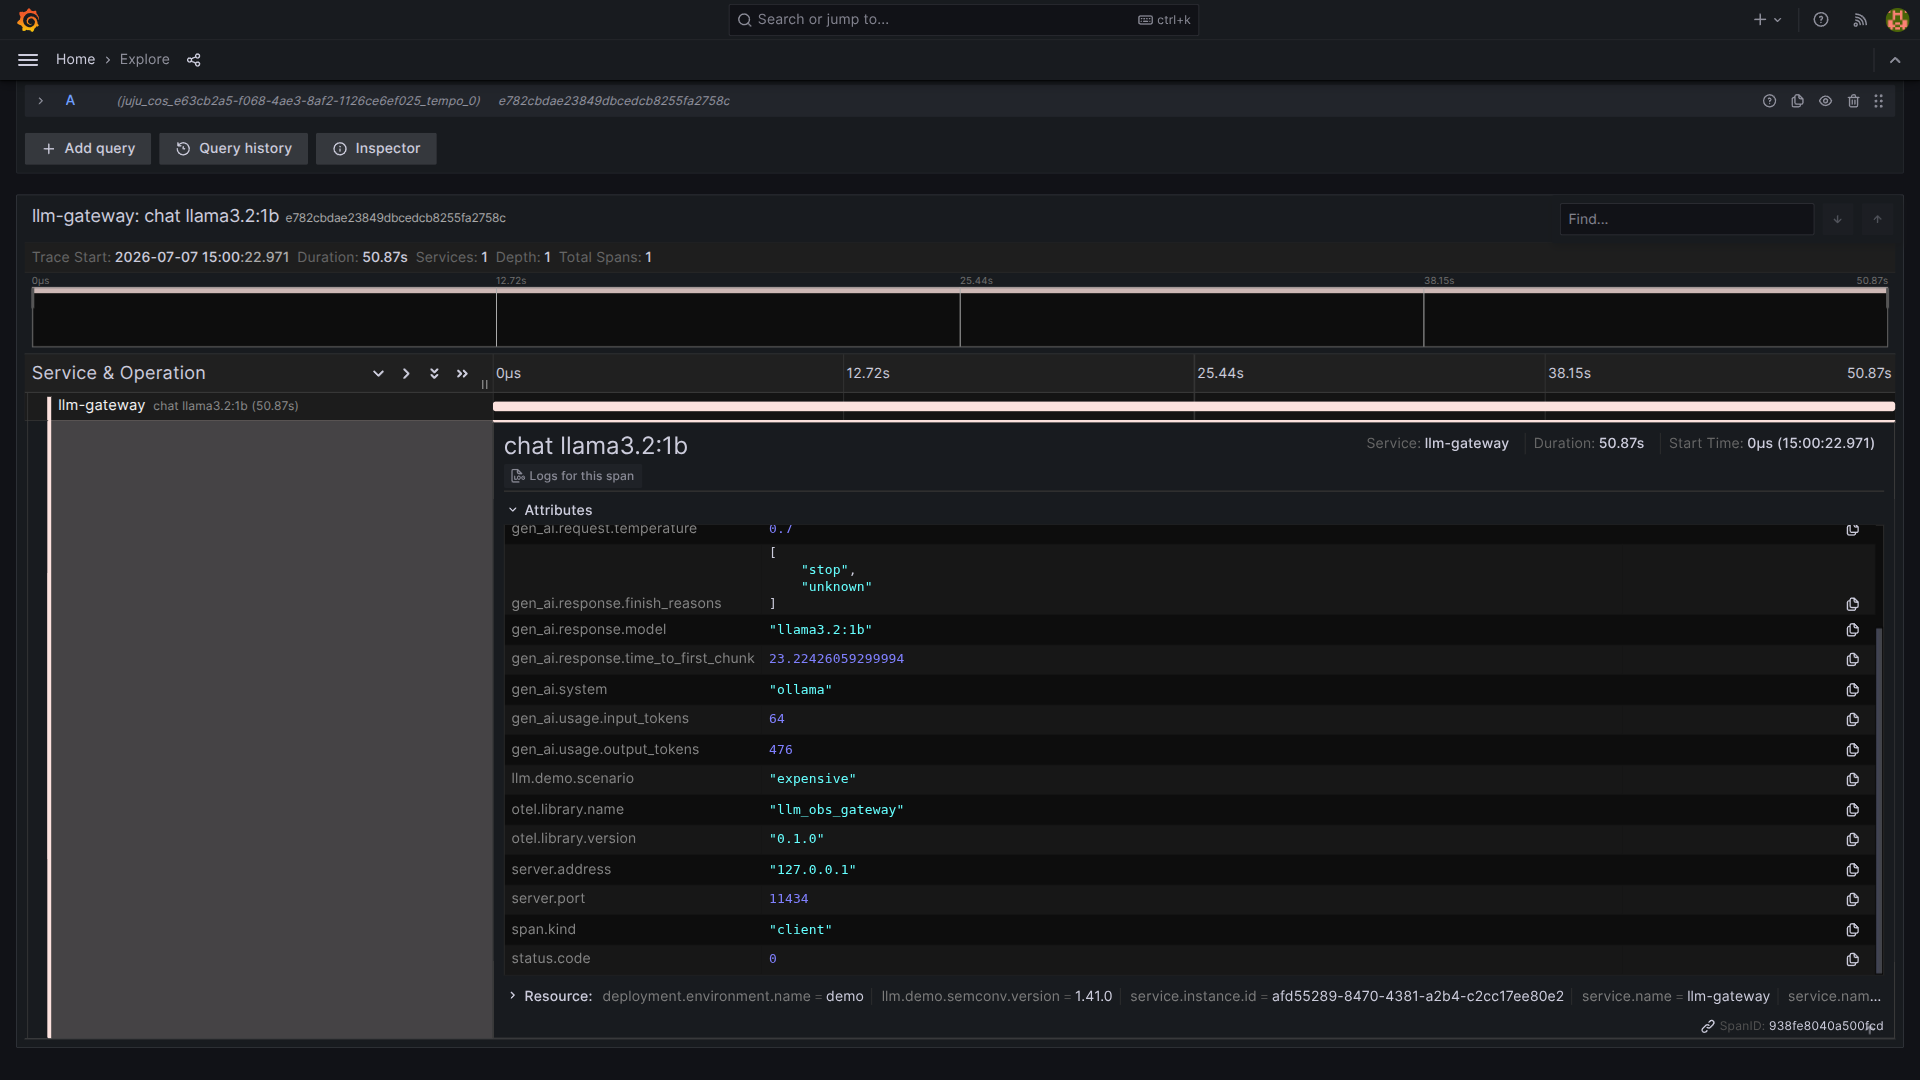
The screenshot records semantic conventions version 1.41.0.
In the current conventions, gen_ai.provider.name
identifies the provider. The visible gen_ai.system field is a legacy attribute
retained by the demo for compatibility.
Correlation does not make instrumentation all-seeing. A trace can explain only
the components that emit spans, and a quality signal can reflect only the
evaluation behind it.
Request-level investigation is one use for these signals. The same measurements
can also be used to compare model builds under matched workloads.
Telemetry can reveal quantization trade-offs
Quantization stores model weights at lower precision. It can make a model
smaller and faster, but it may reduce output quality, as the llama.cpp
documentation explains.
The chart compares eight llama3.2:1b-instruct builds. The bars show generation
speed after the first token. The QA column shows correct answers out of 31.
Every build answered the same questions with temperature set to zero: 10
factual, eight arithmetic, six instruction-following, and seven reasoning. Each
correct answer earned one point.
The score measures correctness on this fixed probe, not overall model quality.
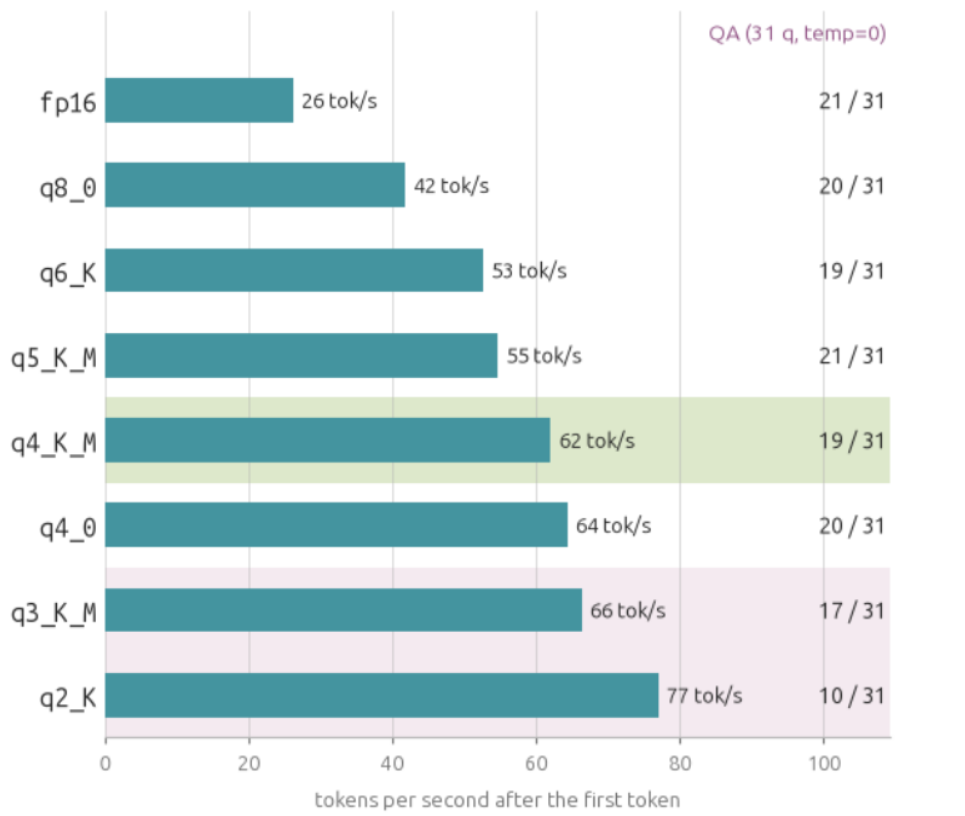
As precision fell, speed rose from 26 to 77 tokens per second. Quality stayed
near fp16 through q4_0, then fell from 17 correct answers at q3_K_M to 10
at q2_K.
The highlighted q4_K_M offered a useful balance: 62 tokens per second, about
2.4 times the fp16 rate, with 19 correct answers instead of 21. Results will
vary by model, hardware, workload, and question set.
Where these signals can help
The useful questions change depending on where a local model runs:
-
Edge and industrial systems. A local assistant on a production line,
gateway, or field device may have limited compute and unreliable connectivity.Timing, resource, and quality signals can help teams compare what fits that
hardware. Canonical has explored AI inference at the edge
and local AI appliances with Ubuntu Core. -
Private or disconnected workflows. A document assistant can keep
inference local when material should not be sent to a hosted model.Operational telemetry can still describe its behaviour while content capture
remains disabled. This pattern appears in Canonical’s example of local LLM
inference, including offline and air-gapped settings. -
Teams comparing models. When several models or builds can serve the same
task, matched requests can compare responsiveness, token use, and observed
quality.This adds workload evidence to decisions about hardware-optimized GenAI
inference.
These signals do not make an application secure, private, or compliant by
themselves. They provide evidence that can support wider engineering and
governance decisions.
Model behaviour becomes evidence
A local LLM can be responsive but unhelpful, accurate but too slow, or efficient
until a more compressed build changes its answers. Timing, token, completion,
and quality signals expose different parts of those trade-offs.
OpenTelemetry provides a common structure and an evolving vocabulary for the
signals. COS Lite brings together metrics, logs, dashboards, and alerts, while
Tempo adds request-level traces.
These tools do not determine what good performance means. They make the model
experience visible so people can set expectations for their task, hardware,
and privacy requirements.