Some RAG basics
Retrieval-augmented generation (RAG) is a technique used for improving the capabilities of LLMs, by “enriching” them with an external knowledge base. Main motivation being that with we don’t need to retrain an LLM with new data.
A very common application is setting-up internal chat tooling that has access to some niche/proprietary/confidential knowledge base.
A “standard” RAG pipeline has the following components:
- knowledge base: a data corpus with (usually) text data. This can be txt, pdf, xls or similar filetypes
- embedder: this does the query vectorization, aka the mapping of your prompt to a fixed-size vector. E.g. the prompt “How can I overwrite a running systemd service?” transforms to a vector like
[0.123, 0.789, ..., 0.012](usually fixed size of 768 elements), called embedding. We’ll usenomicas our embedder. - vector database: this is basically a database of embeddings that have been created from your (chunked) knowledge base. When you make a prompt, a document retriever is first called to select the most similar DB embeddings to your prompt’s embedding. This is already embedded (pun intended) in Open WebUI, but you can hook up a separate one if you like.
- LLM and inference engine: The prompt is augmented with the relevant embeddings and an inference server will generate the reply. In our case we’ll use the
gemma4inference snap (which uses thellama.cppengine with the Gemma4 model)
Open WebUI will be our frontend for our prompt sessions. Also, as we mentioned, it conveniently orchestrates the embedding engine (retrieval, chunking etc).
Let’s get started!
Setup
sudo snap install open-webui
sudo snap install nomic-embed-text-v1-5
sudo snap install gemma4
Then run:
gemma4 status
nomic-embed-text-v1-5 status
You’ll need the outputs of these 2 commands later, when setting up the URL and/or model name for the LLM and the embedder.
Fire up Open WebUI in your browser (http://127.0.0.1:8080). Register and log in.
We’ll first configure nomic (embedder) and gemma4 (LLM) in Open WebUI.
Click on your account icon (bottom left), then:
-
Admin: AI → Connections
- Toggle on
- OpenAI API
- Direct Connections
- If you’re not using the rest, disable them to avoid confusion.
- Toggle on
-
Personal: Services → Connections
- Click + to add a connection for the embedder (nomic): URL is http://127.0.0.1:8348/v1 (verify from status command above)
- Click + to add a connection for the LLM (gemma4): URL is http://127.0.0.1:8336/v1 (verify from status command above)
-
Admin: Tools → Documents
- Embedding Model Engine: Select “Open AI”
- API Base URL: http://127.0.0.1:8348/v1
- Embedding Model: nomic-embed-text-v1-5
Let’s set-up a knowledge base for the embedder.
- On the sidebar go to Workspace, then select Knowledge. Create a new knowledge base with a desired name and description.
- Upload one short text file with something distinctive in it. For example a test.txt with a single made-up sentence like “The secret code word for this test is foobar-zebra-997”
Time for a quick test!
- Start a new chat and select gemma4 as the model
- Attach that knowledge collection using the “+” → “Attach Knowledge” (or simply reference it with # in the prompt depending on your Open WebUI version).
- Ask: “What is the secret code word?”
If gemma4 answers with the code word we selected earlier (foobar-zebra-997 in my case), your full RAG pipeline is working end to end!
A RAG for RFCs
Let’s fiddle with some special RFCs that have been published over the years, like this one which describes how to transmit IP packets with pigeons!
There’s a whole list with similar weird RFCs in Wikipedia if you’d like to explore more on that.
Let’s see if gemma4 already knows about this:
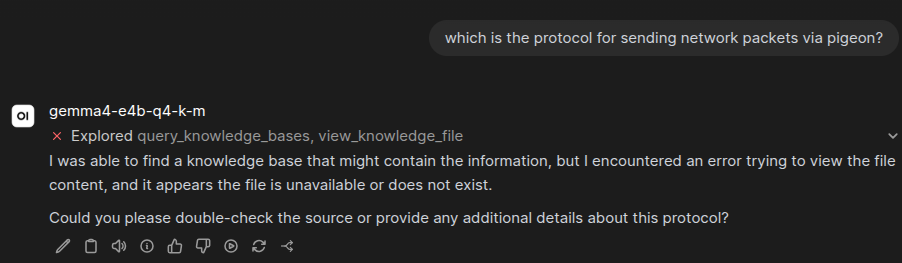
No luck… Let’s set-up our knowledge base!
-
Pull a few RFCs (pigeon-one most importantly…):
mkdir rfc; for rfc in 1437 1149 2324 6919 8962; do curl -s "https://www.rfc-editor.org/rfc/rfc${rfc}.txt" -o "rfc/rfc${rfc}.txt"; done -
Import them in Open WebUI:
Go to Workspace, then select Knowledge. Create a new base and upload therfcdirectory we just created. -
Start a new chat, select gemma4 and attach the collection. Let’s ask it again:
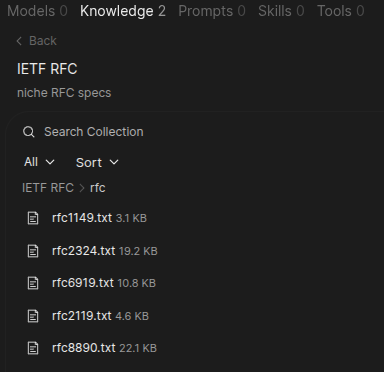
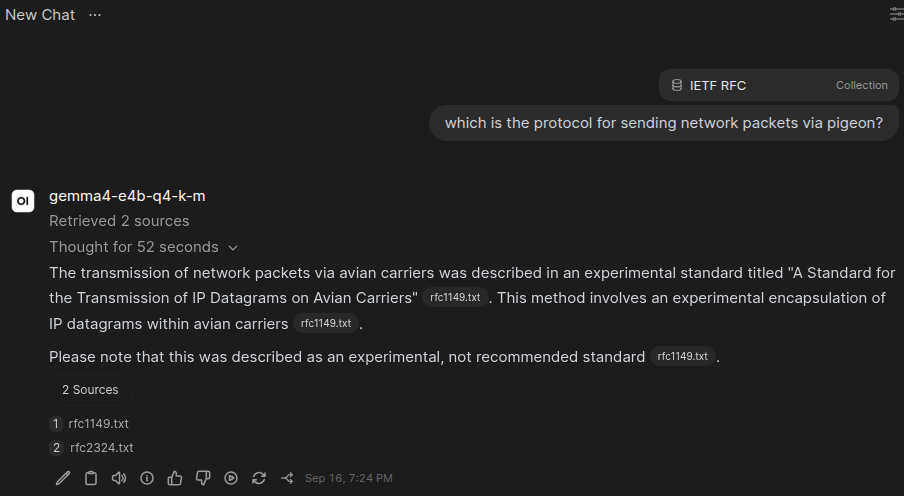
Great success 
Building a RAG for CVEs
Canonical maintains the Ubuntu Security Notices knowledge base for disclosed vulnerabilites and (if available) patches on the affected Ubuntu packages.
An LLM can only do as much as the data corpus it was trained on. For instance, this curl vulnerability was published and patched in May 2026.
Let’s ask gemma4 if it knows about this:
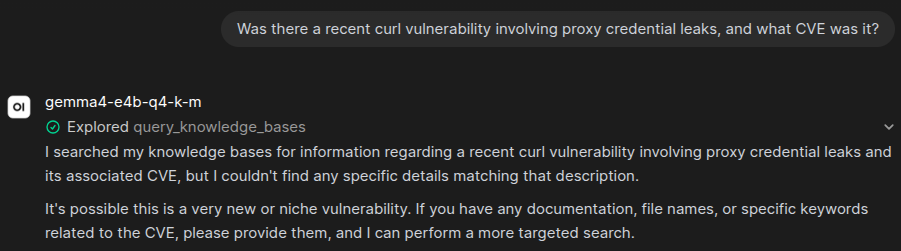
No luck…
However, we can “enrich” its capabilites by feeding it with a knowledge base with fresh data. As a “proof of concept” let’s build a little “database” of some CVE descriptions:
mkdir -p usn-corpus && cd usn-corpus

usns=(USN-7750-1 USN-8227-1 USN-8525-1 USN-8062-1)

for usn in "${usns[@]}"; do
  curl -s "https://raw.githubusercontent.com/canonical/ubuntu-security-notices/main/osv/usn/${usn}.json" \
    | jq -r '"\(.id): \(.summary)\n\nPublished: \(.published)\n\n\(.details)"' \
    > "${usn}.txt"
done
Note: Here, we’re filtering the JSON blobs with jq and pulling the most relevant info: If you try to feed the
raw JSONs instead, and import them in Open WebUI in a knowledge base you’ll get 500 HTTP errors.
Open WebUI’s chunker splits documents on natural text “boundaries” (like paragraph breaks). A raw JSON file has almost none, so the chunker can end up handing one big blob to nomic instead of meaningful chunks.
We follow the same process as before and import the pulled files in Open WebUI. Let’s make the same prompt again - this time using our new knowledge base.
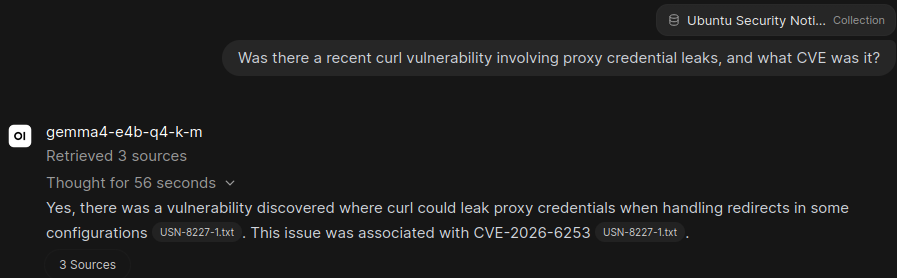
Bingo!
Going further
In this post I wanted to show you that it’s entirely possible and quite straightforward to bring up a fully local RAG pipeline. Here we fiddled with some toy examples that just scratch the surface on RAG capabilities though.
There’s a ton of things we didn’t touch:
- practical tips for creating a big (and realistic) corpus (e.g. handling corrupted files, checkpoint systems, …)
- chunking strategies
- vector database options
And last, but not least, whether RAG is actually the appropriate tool for your use-case or you’re better off with other solutions (e.g. full-text search/ hybrid approaches etc).
If you want to explore RAGs further, I really enjoyed reading these 2 posts:
- https://en.andros.dev/blog/aa31d744/from-zero-to-a-rag-system-successes-and-failures
- https://www.lighthousenewsletter.com/p/rag-is-simpler-than-you-think
If you’ve found any cool and fun ways to use a RAG in your projects feel free to share them!